Different tasks,
different costs of intelligence.
A call-center case from a talk at IE: 1,200 calls a day, a different AI model for each step, and every call now reviewed.
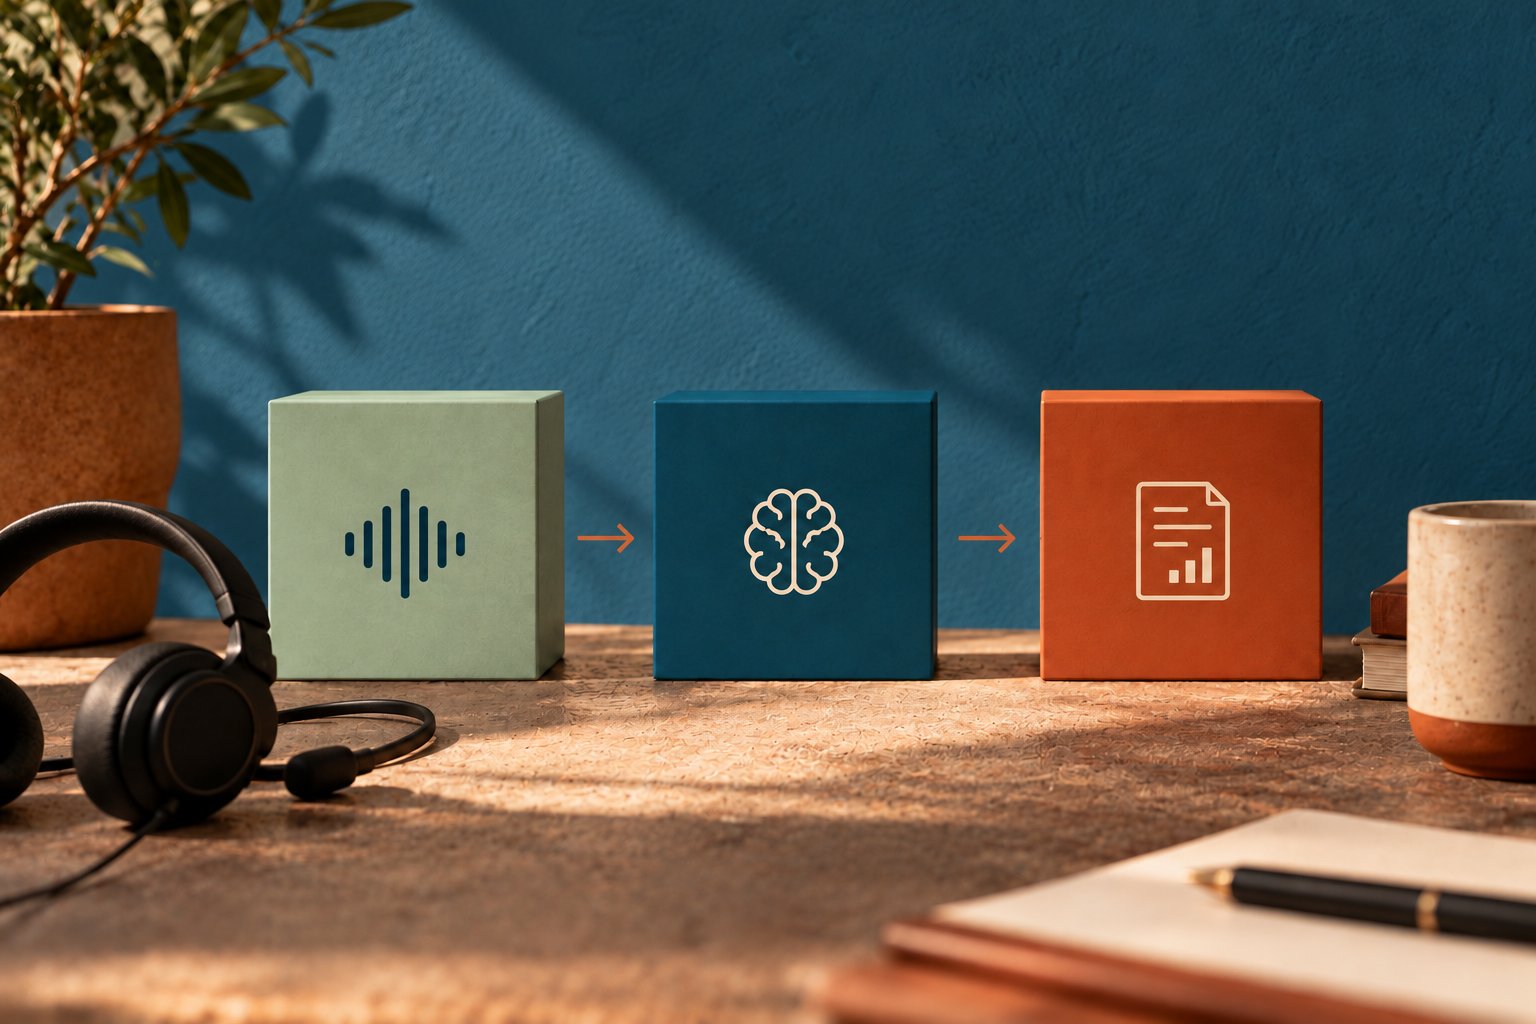
At a talk at IE, a team shared a familiar problem. A sales team makes 1,200 calls a day. The quality team listened to a handful of recordings, filled in a form, and nobody looked at the rest: what was promised, what was left out, what went wrong. Only 2% of calls were ever reviewed, and feedback took three weeks.
Their answer was not one big agent. It was an ecosystem of agents, each running on the model that fit its task, balancing the cost of tokens against the quality of the output. The real workflow has more steps; to keep it simple, think of three.
What the main models cost · US$ per 1M tokens
| Provider | Model | Tier | Input | Output |
|---|---|---|---|---|
| Gemini 4 Argon | Flagship | $2.00* | $10.00* | |
| Gemini 3.8 Flash | Fast | $0.75* | $3.75* | |
| Gemini 3.5 Flash-Lite | Lightest | $0.30 | $2.50 | |
| OpenAI | GPT-6 Astra | Flagship | $10.00 | $50.00 |
| OpenAI | GPT-6.1 Sol | Mid | $2.00 | $10.00 |
| OpenAI | GPT-6 Luna | Lightest | $0.10 | $0.50 |
| Anthropic | Claude Opus 5.5 | Flagship | $4.00 | $20.00 |
| Anthropic | Claude Opus 5 | Previous flagship | $5.00 | $25.00 |
| Anthropic | Claude Sonnet 5.5 | Mid | $2.00 | $10.00 |
| Anthropic | Claude Haiku 5.5 | Lightest | $0.10 | $0.50 |
- 01Match the model to the task.Transcribing, sorting and extracting rarely need a frontier model. Judgement and nuance do.
- 02Price the volume.The step that runs 1,200 times a day decides the bill. Make that one cheap first.
- 03Spend on what people read.The output a manager acts on is where quality pays back.
This call center is not an exception. As companies learn to match each task to its price tag, they stop sending everything to the most powerful model. Frontier models are not losing their place. They are being saved for the steps that need them: judgement, nuance, the output people act on. Everything else moves to cheaper models that are good enough.
The numbers already show it.
The best model is not the smartest one. It is the right one for the step.